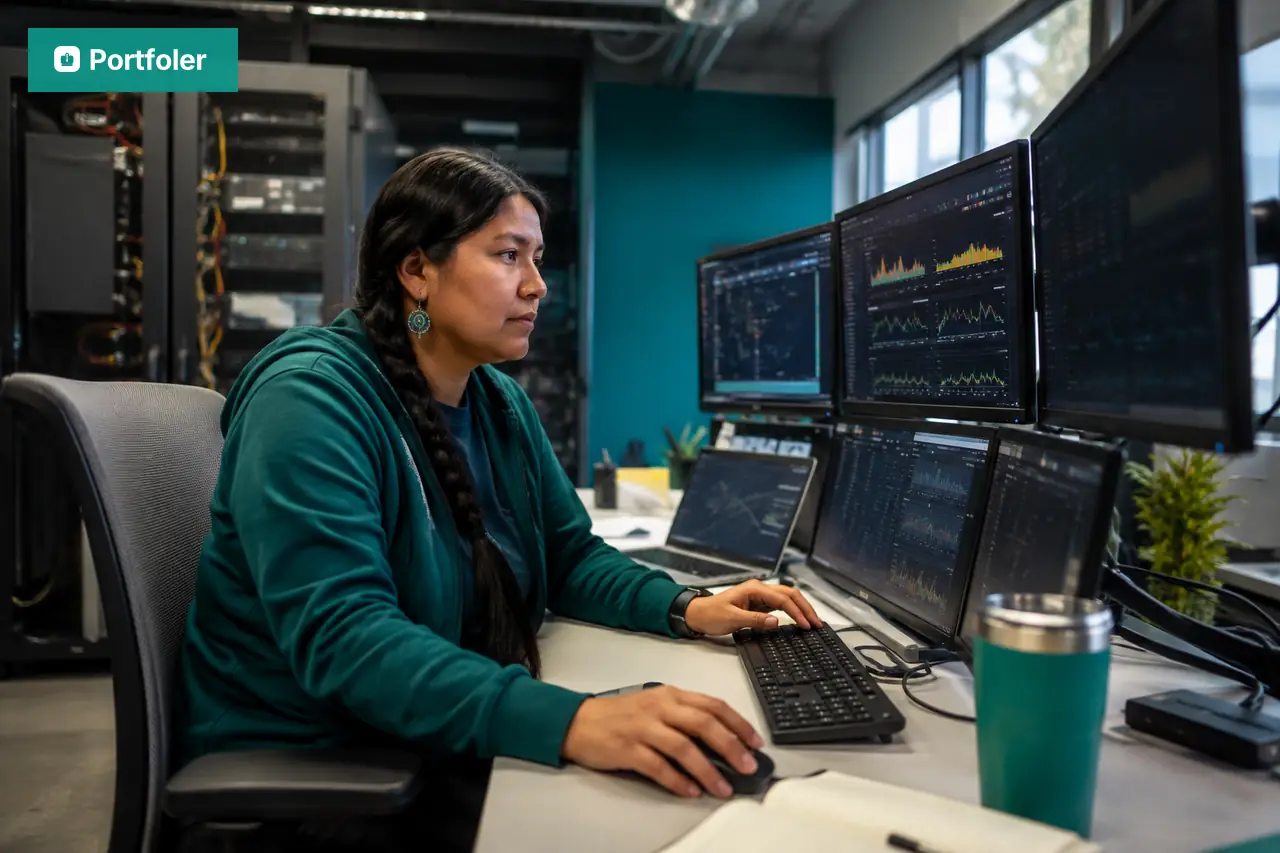
The Site Reliability Engineer (SRE) safeguards the availability and performance of services in production. Sitting at the crossroads of development and operations, they apply an engineering mindset to infrastructure problems so applications stay reliable, even at scale.
Role overview
Born at Google, the SRE role treats reliability as a first-class product feature. The SRE defines service level objectives (SLOs), measures indicators (SLIs) and manages an error budget that balances delivery velocity against system stability.
In practice, they automate whatever can be automated, eliminate repetitive work ("toil"), design resilient architectures and respond to critical incidents. The goal: make outages rare, short and predictable.
Key responsibilities
- Define and track SLOs/SLIs and manage the services' error budget.
- Automate deployment, scaling and disaster recovery.
- Build observability: metrics, logs, traces and alerting.
- Lead incident management and write blameless post-mortems.
- Design high-availability architectures and test resilience (chaos engineering).
- Reduce toil through tooling and automation scripts.
Required skills
Hard skills: Linux, containers and Kubernetes, infrastructure as code (Terraform), a public cloud (AWS, GCP or Azure), scripting (Python, Go, Bash), CI/CD, observability (Prometheus, Grafana), networking and security.
Soft skills: composure under incident pressure, rigour, a service mindset, clear communication and continuous improvement.
Salaries around the world
SRE pay ranks among the highest in tech, driven by the scarcity of the profile and the criticality of the stakes. The salary-by-country table below gives indicative annual gross ranges, in local currency, for an experienced profile.
Career path
- Junior (0 – 3 years): system administration, infrastructure support, first automations.
- Mid (3 – 6 years): ownership of a production scope, observability and CI/CD.
- Senior (6 – 10 years): reliability architecture, major incident command, SLO definition.
- Expert / Lead (10+ years): SRE Lead, Principal Engineer, Head of Reliability / Platform.
Education & training
- Bachelor's to Master's in computer science, networking or systems.
- A DevOps / sysadmin route with growing cloud and automation skills.
- Valued certifications: CKA/CKAD (Kubernetes), AWS/GCP, Terraform Associate.
Industries & opportunities
SREs are sought by high-traffic companies: SaaS, fintech, e-commerce, gaming, cloud platforms and telecoms. Cloud migration and the rise of distributed architectures sustain strong demand.
In short
A strategic, demanding and very well-paid role at the heart of digital service reliability. If you can blend software engineering with large-scale operations, create your profile on Portfoler.com and connect with companies hiring SRE talent.
 United States
 United Kingdom
 Germany
 France
 Canada
 United Arab Emirates
 Morocco
 India
 Spain
 Australia